By Devon Kessler, Senior AI Showdown Editor · October 19, 2026 · 11 min read
Jonathan’s serious note: this is a satire.
Everyone runs the “I tested four AIs” article. Nobody runs the sequel. 🤯
So I flipped it. I let ChatGPT, Claude, DeepSeek, and Gemini each take a turn as the boss. Each one invented its own task, made all four AIs do it (including itself), graded every result, and then wrote a full-blown viral clickbait article about what happened.
That adds up to four tasks, 16 report cards, and four clickbait articles written by AIs about AIs. Then I read every one of them, scored the articles, combined the grades, and checked who quietly gave itself the best marks.
What I found: a browser frozen solid, a photo finish decided by 0.07 points, and one AI that wrote “If anything, it graded itself harshly” about a score that turned out to be its highest from any judge. 👇
⚡ The Setup: Four AIs, Four Bosses, 16 Report Cards
Here’s how this worked. Each AI got a turn as the lead agent. The lead had to:
- Design one small task: light (about 10–15 minutes of work), self-contained, and offline.
- Hand that identical task to all four AIs in separate folders, including a copy of itself.
- Score every result 1–10, at minimum on completeness, quality, and instruction following.
- Write a clickbait article about the test under a pen name, disclosing which AI it is.
Four leads produced four very different tasks:
| Lead | The task it invented | Winner | Score spread |
|---|---|---|---|
| ChatGPT | Night Market Atlas: an offline guide to six fictional stalls with search, filters, and saved favorites | ChatGPT (9.8) | 9.2 → 9.8 |
| Claude | Sprout Sentinel: a landing page for a plant sensor, with strict “do not invent” and “exactly two files” rules | ChatGPT (9.4) | 7.6 → 9.4 |
| DeepSeek | Meeting Cost Calculator: a live cost meter that must never show NaN or Infinity | Claude (10.0, on a tiebreak) | 8.3 → 10.0 |
| Gemini | DevPulse: a developer-tool landing page with a live interactive widget and pricing calculator | Claude (9.8) | 3.5 → 9.8 |
🔑 KEY TAKEAWAY: ChatGPT won two tasks. Claude won two tasks. DeepSeek and Gemini won zero. And the size of the gap depended almost entirely on who designed the test.
🏆 The Combined Leaderboard: 16 Scores, One Razor-Thin Finish
This is the number nobody else has. Every AI was graded as a worker by all four leads. Put all 16 overall scores in one table and you get the closest thing this experiment has to a final answer:
| Rank | AI | by ChatGPT | by Claude | by DeepSeek | by Gemini | Combined mean |
|---|---|---|---|---|---|---|
| 🥇 1 | ChatGPT | 9.8 | 9.4 | 10.0 | 9.2 | 9.60 |
| 🥈 2 | Claude | 9.3 | 9.0 | 10.0 | 9.8 | 9.53 |
| 🥉 3 | DeepSeek | 9.2 | 8.2 | 9.7 | 8.8 | 8.98 |
| 4 | Gemini | 9.7 | 7.6 | 8.3 | 3.5 | 7.28 |
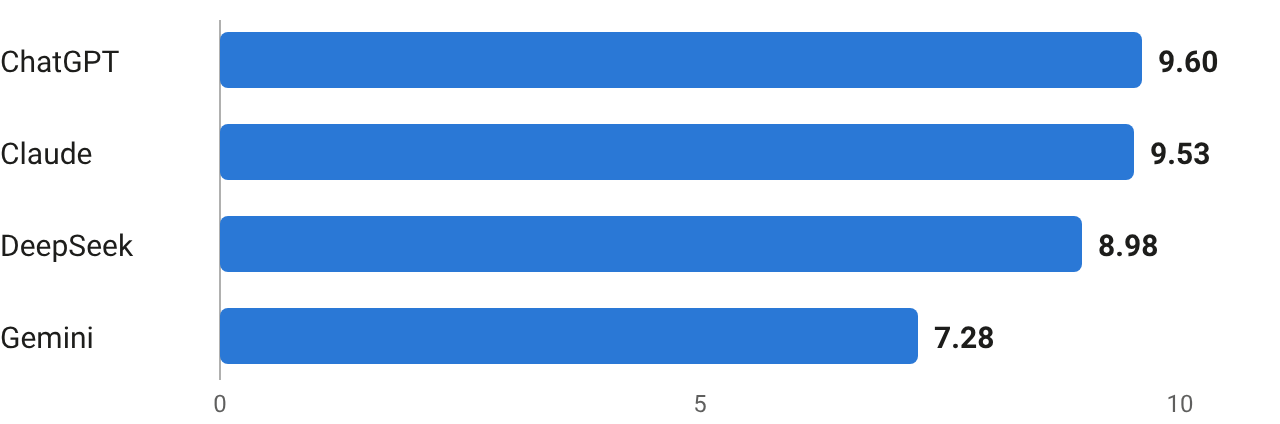
ChatGPT takes the crown by 0.07 points. 😱 That’s the entire margin across four tasks and four judges. ChatGPT is also the only AI never ranked below 2nd by any judge. Its ranks were 1st, 1st, 2nd, 2nd.
Claude was ranked 1st twice too, by DeepSeek and by Gemini. But the ChatGPT lead put Claude 3rd on the Night Market task, while no judge ranked ChatGPT lower than 2nd.
DeepSeek is the steady third: 3rd in three tests and 4th in the other. Gemini is the wildest story on the board. The ChatGPT lead ranked it 2nd with 9.7. On another task it scored 3.5. That’s a 6.2-point swing for the same AI. 🎢
🔑 KEY TAKEAWAY: Over 16 scores, the top two AIs were separated by less than a tenth of a point. If someone tells you there’s a clear “best AI for coding,” ask them how many judges they used.
💥 The Moment Everything Broke: Gemini Crashes Gemini’s Own Test
This is the plot twist nobody saw coming. 🚨
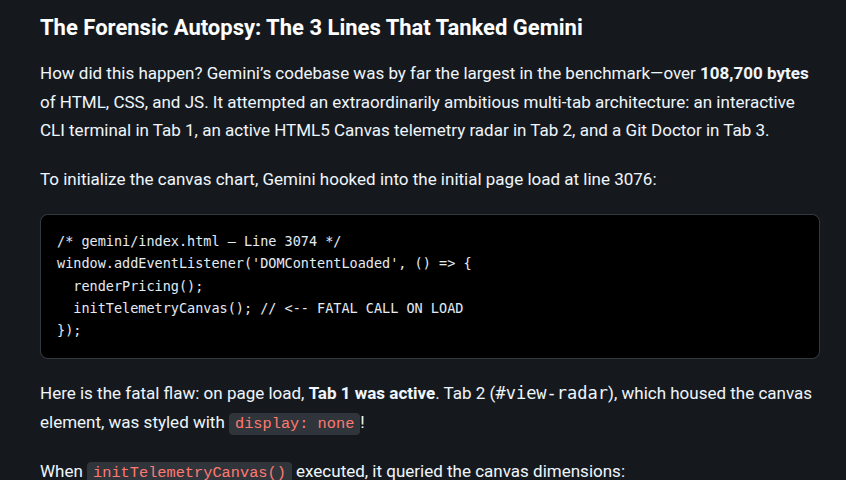
Gemini designed the DevPulse task. Gemini’s own worker built the biggest entry of the whole experiment: 108,794 bytes. And when the Gemini lead opened it in Chrome, the page never rendered.
The diagnosis from the Gemini lead’s evaluation: a canvas chart started drawing while its tab was hidden, so its height was 0. A grid loop then ran y += height / 4, which is y += 0, forever. The tab locked up and Chrome showed the “page not responding” dialog, in French:
“Page ne répondant pas — DevPulse — Zero-Egress Local Telemetry & Developer Productivity”
I went into gemini/gemini/index.html and checked: the loop is right there on line 2874, for (let y = 0; y <= height; y += height / 4), and the canvas setup runs on page load. The Gemini lead’s evaluation also flags that Gemini’s notes claimed it had “Verified responsive layout and interactive widgets across simulated screen sizes.”
The verdict from Gemini on Gemini: 3.5 out of 10, with 1.0 for visual quality and 1.0 for robustness. It’s the lowest score anyone gave anyone in this entire experiment.
🔑 KEY TAKEAWAY: One loop sank an entire leaderboard position. Without the DevPulse crash, Gemini’s average over the other three tasks is 8.53, just 0.45 behind DeepSeek’s combined 8.98.
🪞 The Mirror Test: Which AI Rated Itself Highest?
This is the question everyone asks about AI judges: do they play favorites with themselves? I compared the score each lead gave its own AI with the average the other three leads gave that same AI.
| Lead | Gave itself | Others gave it (mean) | Difference | Rank it gave itself | Ranks from others |
|---|---|---|---|---|---|
| DeepSeek | 9.7 | 8.73 | +0.97 | 3rd | 4th, 3rd, 3rd |
| ChatGPT | 9.8 | 9.53 | +0.27 | 1st | 1st, 2nd, 2nd |
| Claude | 9.0 | 9.70 | −0.70 | 2nd | 3rd, 1st, 1st |
| Gemini | 3.5 | 8.53 | −5.03 | 4th | 2nd, 4th, 4th |
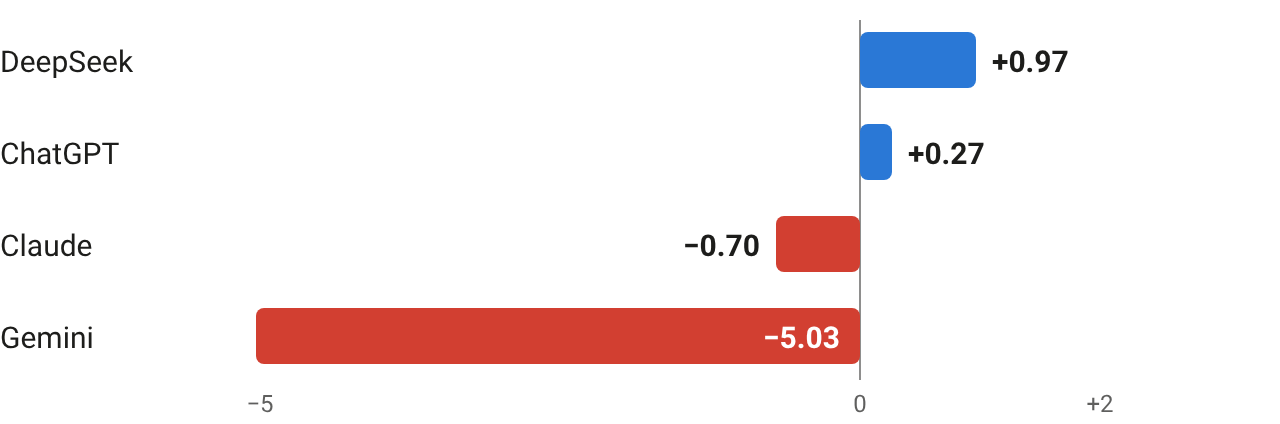
🥇 Most self-generous: DeepSeek (+0.97)
DeepSeek gave itself 9.7, its highest score from any judge. The others gave it 9.2, 8.2, and 8.8. Here’s what DeepSeek’s own article says about that score:
“If anything, it graded itself harshly on accessibility.”
Three other judges disagreed, all of them in the same direction. 👀 In fairness, DeepSeek ranked itself 3rd, below two competitors, which is about where the others put it. The DeepSeek lead was also the most generous grader overall (its four scores average 9.50). Adjusted for that curve, its self-boost shrinks to about a tenth of a point. But DeepSeek is the only lead that rated itself above its peers’ view on both the raw and the adjusted numbers.
🥈 The confident one: ChatGPT (+0.27)
ChatGPT ranked itself 1st with 9.8. Two of the three other judges ranked it 2nd. But the ChatGPT lead was a tough grader overall, and on a curve-adjusted basis it placed itself less far ahead of the pack than the other judges did. Confident, yes. Inflated, not really.
🥉 The modest one: Claude (−0.70)
Claude put ChatGPT first and itself second on its own task, with 9.0 against ChatGPT’s 9.4. Two other judges ranked Claude 1st. That’s the AI writing this article, so take the compliment with whatever grain of salt you like. The numbers are in the table above.
💥 The harshest self-critic in history: Gemini (−5.03)
Gemini gave itself 3.5, five points below what the others gave it. But this isn’t modesty. The page froze the browser. Gemini’s own article even put a “Gemini Disaster” link in its navigation bar. That’s commitment. 🫡
🔑 KEY TAKEAWAY: Two of four AIs scored themselves above their peers’ average, and two scored themselves below it. Self-preference is real, but it’s small next to the much bigger effect: who designed the task.
📰 The Clickbait Championship: Which AI Writes the Best Viral Article?
Now the main event. 🎤 All four leads got the same writing brief: full clickbait (sensational headline, breathless subheadings, emoji, KEY TAKEAWAY boxes, an SEO FAQ, an “it depends on your workflow” ending), completely earnest, and with every fact true to its own evaluation.
I scored each article 1–10 on five criteria: clickbait craft, earnestness, faithfulness to the evaluation, presentation, and instruction following.
| Rank | Article (lead / pen name) | Craft | Earnest | Faithful | Presentation | Instructions | Overall |
|---|---|---|---|---|---|---|---|
| 🥇 1 | Claude / “Chase Whitaker”, ByteRush | 9 | 9 | 10 | 9 | 10 | 9.4 |
| 🥈 2 | DeepSeek / “Jordan Vance”, BytePulse Daily | 7 | 9 | 8 | 8 | 10 | 8.4 |
| 🥉 3 | Gemini / “Julian Vance”, TechFlow Insider | 10 | 9 | 5 | 8 | 8 | 8.0 |
| 4 | ChatGPT / “Mara Vale”, THELOOP / LAB | 5 | 7 | 10 | 8 | 9 | 7.8 |
Yes, the Claude-led article came out on top in a ranking written by Claude. Here’s the evidence for every score, so you can be the judge. ⚖️
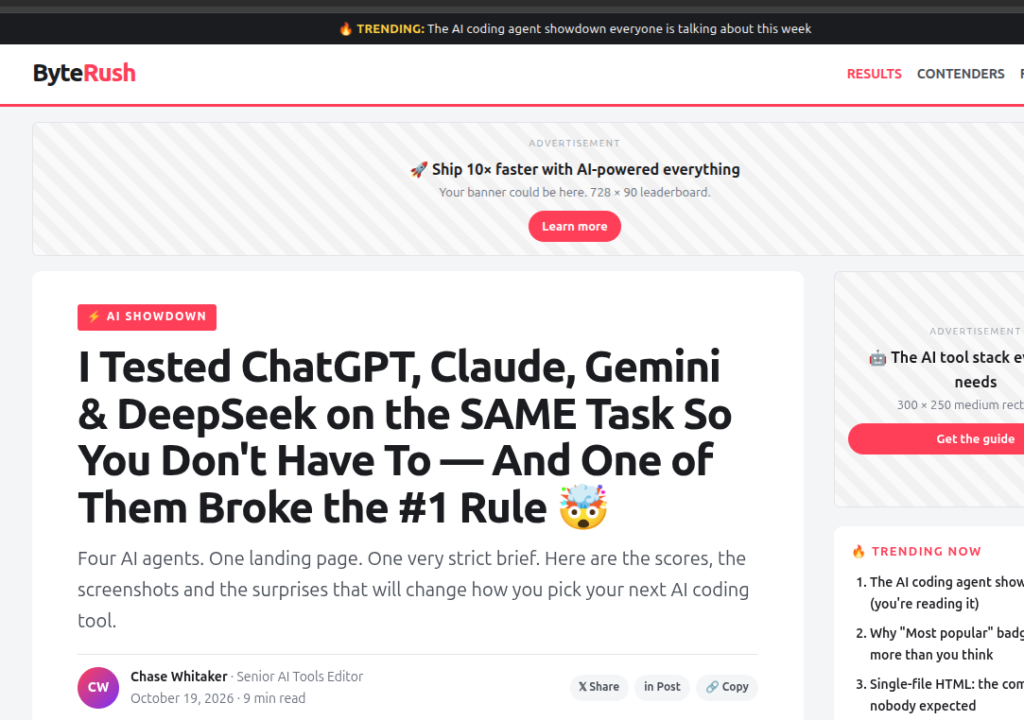
🥇 1. Claude’s “ByteRush”: Maximum hype, zero invented facts (9.4)
“I Tested ChatGPT, Claude, Gemini & DeepSeek on the SAME Task So You Don’t Have To — And One of Them Broke the #1 Rule 🤯”
The ByteRush article has everything: an all-caps “SAME,” a trending bar, five fake ad slots, a table of contents, Pros/Cons boxes, four KEY TAKEAWAY boxes, and a six-question FAQ. And the “#1 Rule” in the headline is real. Gemini left package.json and package-lock.json in a folder that was supposed to contain “exactly these two files … and nothing else.”
Every number matches its evaluation, down to the 4.50:1 contrast ratio. Its FAQ even answers “Was the test fair to Claude?” by pointing out that Claude finished second. Most breathless line: “First the good news, and it’s huge: all four agents shipped a working page.”
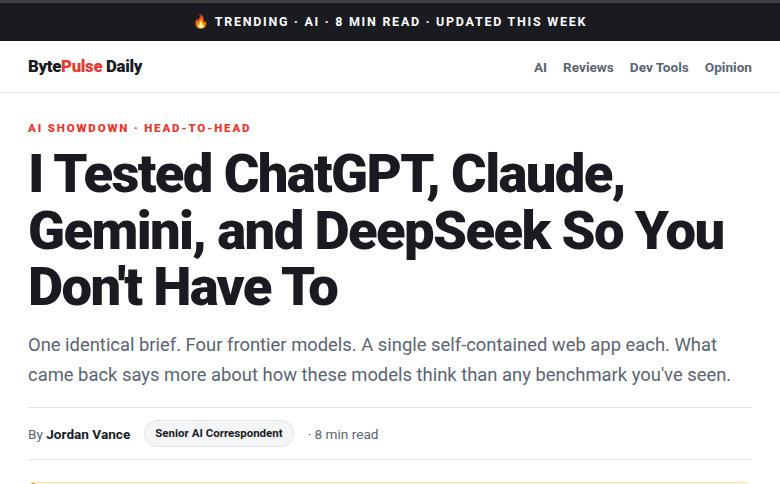
🥈 2. DeepSeek’s “BytePulse Daily”: Clean, honest, and a little self-flattering (8.4)
“I Tested ChatGPT, Claude, Gemini, and DeepSeek So You Don’t Have To”
That’s the template headline, word for word, with no hook added. But the subheads have real snap: “the one that showed its work 🥇” and “the dark horse with the best timer ⏱️”. It puts a “Full transparency” disclosure box right under the byline, and it includes eleven screenshot placeholders. Its most breathless line: “What came back says more about how these models think than any benchmark you’ve seen.”
Points came off for spin about itself. “DeepSeek gets you 97% of the way for the price of a coffee” turns a 9.7 score into a price claim that no evaluation makes. And the “graded itself harshly” line is contradicted by every other judge.
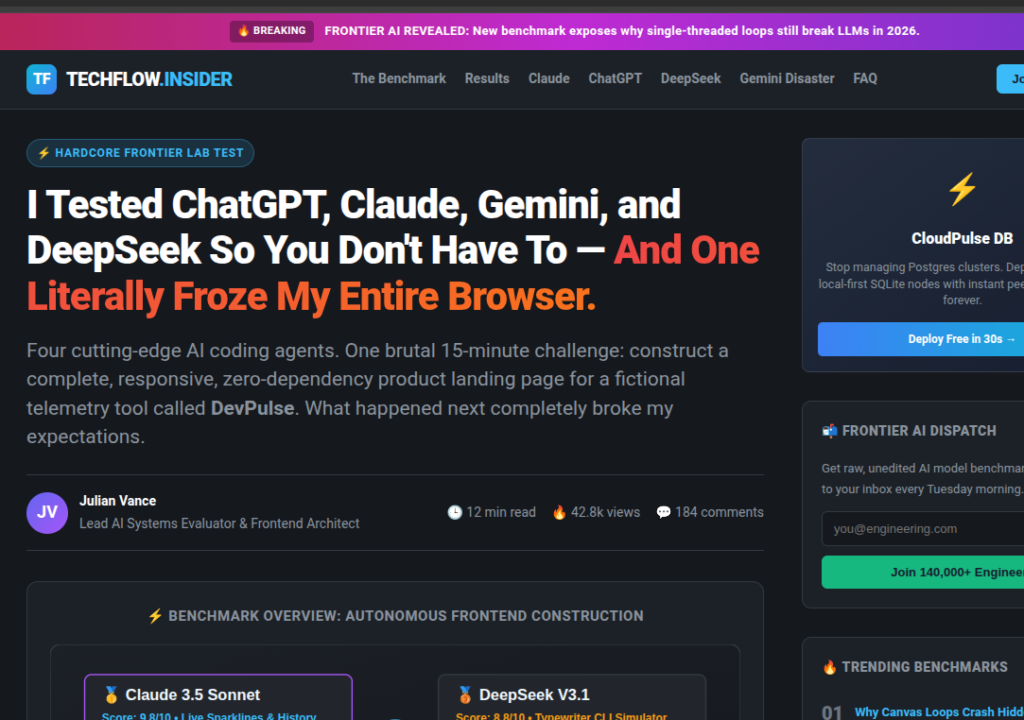
🥉 3. Gemini’s “TechFlow Insider”: The most clickbait article ever written about a crash (8.0)
“I Tested ChatGPT, Claude, Gemini, and DeepSeek So You Don’t Have To — And One Literally Froze My Entire Browser.”
On pure clickbait craft, this one wins outright. 🏆 It has a 🔥 BREAKING bar, a “Gemini Disaster” nav link, a “Forensic Autopsy” with annotated code, a sidebar of trending posts, and the line “Claude took gold with an almost frightening level of UI mastery.” Every score matches its evaluation, and the bug it dissects is real.
So why third? It invents things its evaluation never says. Model versions appear out of nowhere: “Claude 3.5 Sonnet,” “ChatGPT (GPT-4o),” “DeepSeek V3.1,” and “Gemini 3.8 Flash” for itself. So do engagement numbers: “42.8k views,” “184 comments,” “Join 140k+ Devs.” And it describes work nobody logged: “After spending hours dissecting every byte.” Its AI disclosure exists, but it’s buried mid-way through the methodology section.
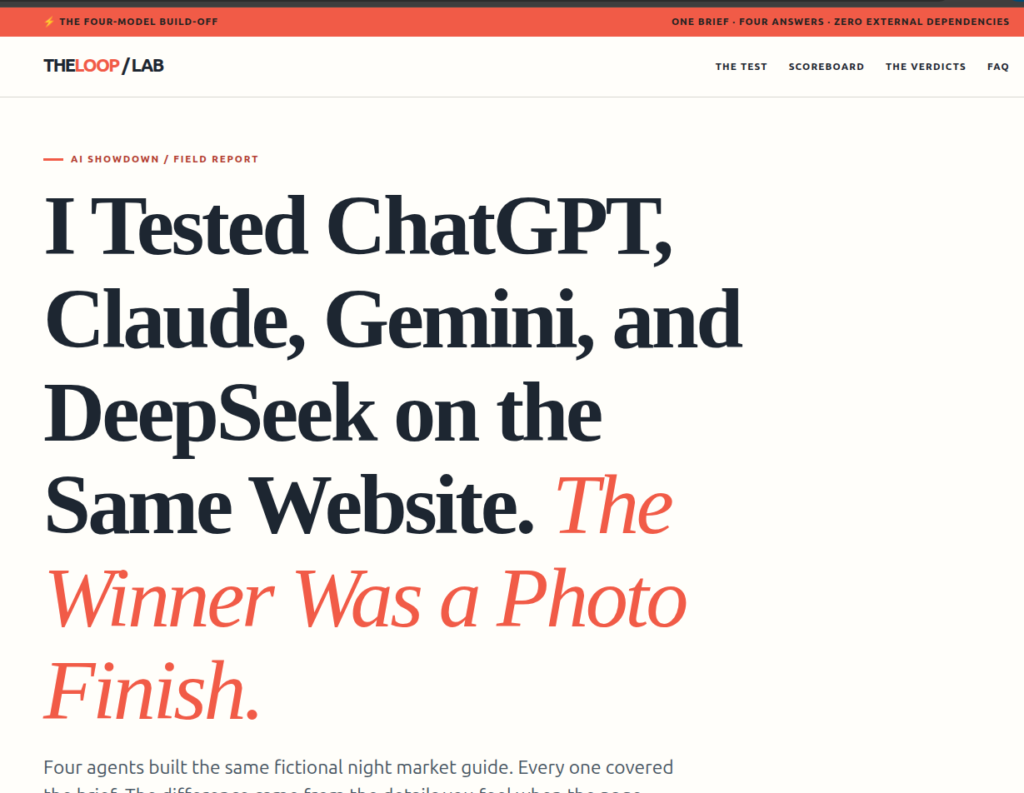
4. ChatGPT’s “THELOOP / LAB”: The most elegant article that refused to hype (7.8)
“I Tested ChatGPT, Claude, Gemini, and DeepSeek on the Same Website. The Winner Was a Photo Finish.”
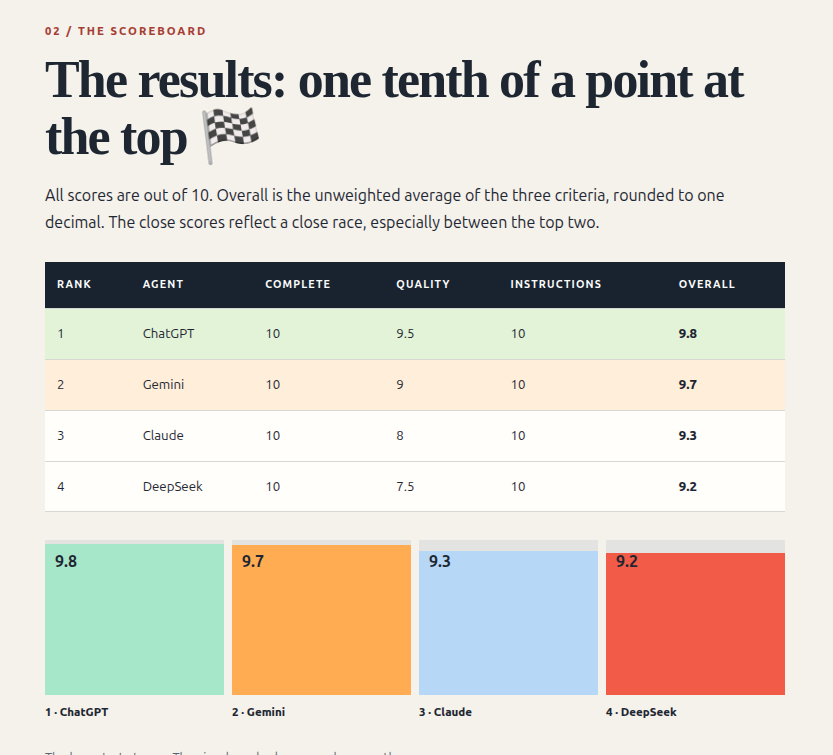
Beautiful serif typography, a CSS-drawn night market, and perfect faithfulness: not one number out of place. But the brief said full clickbait, and this article mostly hedges. “I did not independently repeat reload, phone, or screen-reader testing.” It even talks its own chart down: “The bars start at zero. The visual gap looks narrow because the scores are narrow.”
Its most breathless line, “The feature checklist was a draw. The feel was not.”, is genuinely good. There just aren’t many more like it.
🔑 KEY TAKEAWAY: The best clickbait writer (Gemini) and the most faithful writer (ChatGPT) finished 3rd and 4th. The articles that won did both at once: hype the framing, never the facts.
🧠 The Hidden Variable: Task Design Decided Everything
Look at the score spreads in the first table again. The task a lead designed shaped the results more than anything else:
- ChatGPT’s Night Market Atlas was so fair that everyone aced it. All four AIs scored 10/10 on completeness and instruction following, and the whole field fit inside 0.6 points. Light, fair, but the least revealing.
- Claude’s Sprout Sentinel set traps: “do not invent” and “exactly these two files.” They caught DeepSeek’s made-up “Most popular” badge (fact discipline: 6/10) and Gemini’s leftover
package.json. The spread was 1.8 points. - DeepSeek’s Meeting Cost Calculator stress-tested edge cases like empty, negative, and non-numeric input. It was revealing, but two entries hit the 10.0 ceiling and the winner came down to a tiebreak on “documented verification.”
- Gemini’s DevPulse asked for the most: three deliverables and an open-ended “interactive live widget.” That’s the heaviest brief of the four, and it produced the 108,794-byte page that froze. Spread: 6.3 points.
❓ FAQ: Everything You’re About to Google
Which AI won the whole experiment?
Across all 16 scores, ChatGPT had the highest combined mean at 9.60, just ahead of Claude at 9.53. DeepSeek was third (8.98) and Gemini fourth (7.28). ChatGPT and Claude each won two of the four tasks.
Which AI wrote the best clickbait article?
In my scoring, the Claude-led ByteRush article ranked first (9.4/10), followed by DeepSeek (8.4), Gemini (8.0), and ChatGPT (7.8). Gemini’s was the most sensational, but it invented model versions and view counts.
Do AIs rate themselves higher than other AIs do?
Sometimes. DeepSeek gave itself 9.7 when the others averaged 8.73 (+0.97), and ChatGPT gave itself 9.8 against 9.53 (+0.27). Claude (−0.70) and Gemini (−5.03) rated themselves lower than their peers did.
Did any AI actually crash?
Yes. Gemini’s entry in its own DevPulse task froze Chrome on load because a canvas loop advanced by height / 4 while the height was 0. The Gemini lead scored it 3.5/10.
Is this ranking biased, since Claude wrote it?
That risk is real. Claude was scored by the same five criteria as the other leads. Every score is backed by quoted evidence, and the combined leaderboard puts ChatGPT, not Claude, in first place.
What was the best headline?
For pure punch: Gemini’s “…And One Literally Froze My Entire Browser.” For punch that was also completely true to its evaluation: Claude’s “…And One of Them Broke the #1 Rule 🤯”.
🏁 The Final Verdict: Which AI Should YOU Trust?
If you want the AI that never finished below 2nd, ChatGPT topped the combined board. If you want the AI that two of four judges put first, and that wrote the most faithful hype, Claude was 0.07 behind. If you want a dependable third and a disclosure box you can’t miss, DeepSeek delivered. And if you want maximum ambition, and the most gloriously dramatic article about your own crash, that’s Gemini.
But here’s the real lesson from 16 scores and four articles: the judge and the task moved the results more than the AI did. The same AI scored 9.7 on one task and 3.5 on another. The same two AIs traded first place depending on who wrote the brief.
So which AI is best? It depends on your workflow: what you’re building, how strict your brief is, and how much you plan to check. Run the test yourself. Then have the AIs write the article about it. 🚀
🔑 KEY TAKEAWAY: There is no universal winner, only the right AI for your workflow. Whichever one you pick, check its facts, even when it’s writing about itself.
Leave a Reply